The Inference Hardware Revolution of 2026

The Inference Hardware Revolution of 2026. CREATE AN ACCOUNTSIGN INComputingMagazineFeature The AI Inference Revolution Is Here Today’s tidal wave of queries is forcing hardware makers to pivotMatthew S.
What happened
IEEE. orgIEEE XploreIEEE StandardsIEEE Job SiteMore SitesSign InJoin IEEEThe AI Inference Revolution Is HereShareFOR THE TECHNOLOGY INSIDERExplore by topicAerospaceAIBiomedicalClimate TechComputingConsumer ElectronicsEnergyHistory of TechnologyRoboticsSemiconductorsTelecommunicationsTransportation IEEE Spectrum FOR THE TECHNOLOGY INSIDERTopicsAerospaceAIBiomedicalClimate TechComputingConsumer ElectronicsEnergyHistory of TechnologyRoboticsSemiconductorsTelecommunicationsTransportationSectionsFeaturesNewsOpinionCareersDIYEngineering ResourcesMoreNewslettersSpecial ReportsCollectionsExplainersTop Programming LanguagesRobots Guide ↗IEEE Job Site ↗For IEEE MembersCurrent IssueMagazine ArchiveThe InstituteThe Institute ArchiveFor IEEE MembersCurrent IssueMagazine ArchiveThe InstituteThe Institute ArchiveIEEE SpectrumAbout UsContact UsReprints & Permissions ↗Advertising ↗Follow IEEE SpectrumSupport IEEE SpectrumIEEE Spectrum is the flagship publication of the IEEE — the world’s largest professional organization devoted to engineering and applied sciences.
In 2026, inference—the use of trained models to produce code, write essays, or make images of ourselves as elves—has come to the forefront. “All that any chief information officer wants to talk about is inference. ” Nvidia CEO Jensen Huang, speaking at the company’s GTC 2026 conference, touted this change as the “inflection point of inference. ”Part of what’s caused the shift is very simple: LLMs are becoming useful, so people are using them.
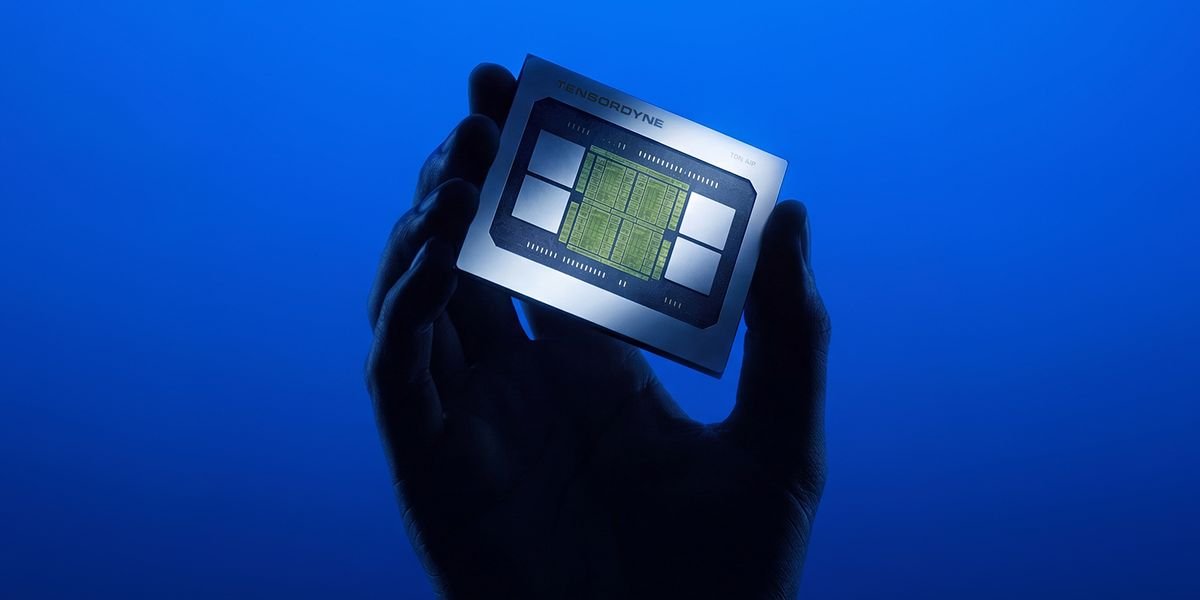
These big moves from tech giants signal that in order to support the inference demand, we’re going to need a very different mix of hardware than experts may have expected even a couple of years ago. But Sudeep Bhoja, founder and CTO of the inference-hardware company d-Matrix, explains that inference adds new challenges. As a result, the movement of all this data through memory often requires more bandwidth than inference hardware has available. Smith7h12 min readVerticalTensordyne’s Napier chip is designed to accelerate AI inference.
The wider picture
In response to a user’s query, they run inference not just once but multiple times, reprompting themselves in a process called chain of thought. Adding even more to the world’s inference workload, the rise of agentic AI has resulted in inference running not just as a real-time response to a user’s query but also around the clock, working autonomously toward a user-defined goal. However, Amazon Web Services chose to break up AI inference into two parts, with Trainium running the more computationally complex portion and Cerebras’s wafer-scale engine taking on the more memory-intensive portion.
AmazonThe resulting explosion in inference demand has led to unexpected alliances among tech giants. Nvidia bought key talent and intellectual property from AI-inference startup Groq in a controversial deal worth US $20 billion. Although they might seem similar, AI training and AI inference are computationally different. How does AI inference differ from AI training? You might think that AI inference is less computationally demanding because the backpropagation calculations used to update parameters are eliminated.
What has been reported
This is where the autoregressive nature of the model works against inference speed. Memory’s role in inferencingShahriar “Sha” Rabii, former head of silicon engineering at Meta and cofounder of the AI startup Majestic Labs, says idled processors are why many companies that are trying to improve AI-inference performance are laser-focused on memory. However, their companies imagine different solutions. d-Matrix’s second-generation AI accelerator, Raptor, aims to improve inference performance by minimizing the distance between compute and memory.
The GPUs in most current AI-inference deployments do this by placing high-bandwidth memory (HBM) around the perimeter of the GPU. This is great for training, but for inference, the amount of memory you can stack this way and the bandwidth it can provide leave something to be desired. d-Matrix’s stacked-die architecture Memory bandwidth—how quickly data can be read from memory to logic—is a major bottleneck in AI inference. HBM4, the latest version of HBM memory, is now in production and will be used by Nvidia’s Vera Rubin GPU, which is expected to ship in the second half of 2026.
Hoshik Kim, head of memory-systems research at SK Hynix, says HBM4 “will decisively break the memory bottlenecks constraining AI inference today” by doubling HBM’s maximum memory bandwidth and increasing the amount of HBM memory per stack. Combining chips for faster inferenceThe big players—Nvidia and Amazon—are going for an all-chips-on-deck approach.
What happens next
Nvidia’s GPUs and Amazon’s Trainium training accelerators are still great for part of the inference workload: the prefill stage, where all the context keys and values are calculated. Nvidia purchased intellectual property and hired talent from Groq at the end of 2025, and just three months later at the Nvidia’s GTC 2026 conference, Jensen Huang unveiled the Nvidia Groq 3 language-processing unit (LPU). AI inference, however, has ignited new interest in SRAM as a means of bringing the model weights stored in memory closer to compute.
Nvidia’s two-chip approach to inference Nvidia also plans to split the inference workload across two chips. Our articles, videos, and infographics inform our readers about developments in technology, engineering, and science. A public charity, IEEE is the world's largest technical professional organization dedicated to advancing technology for the benefit of humanity. Enjoy more free content and benefits by creating an account Saving articles to read later requires an IEEE Spectrum account The Institute content is only available for members Downloading full PDF issues is exclusive for IEEE Members Downloading this e-book is exclusive for IEEE Members Access to Spectrum 's Digital Edition is exclusive for IEEE Members Following topics is a feature exclusive for IEEE Members Adding your response to an article requires an IEEE Spectrum account Create an account to access more content and features on IEEE Spectrum , including the ability to save articles to read later, download Spectrum Collections, and participate in conversations with readers and editors.